We need to talk about the prompt engineering obsession. Somehow the standard advice for a broken AI integration has become “tighten the prompt.” I thought we’d moved past this, but I still see devs spending days arguing with a model to “return only JSON” when the problem is architectural, not linguistic. What you need is an LLM Control Layer.
I’ve been there. You ship a feature that uses GPT-4 to categorize WooCommerce orders, and it looks perfect locally. Then a user enters a string with unescaped characters, the model wraps the JSON in markdown backticks, and your PHP throws a fatal error because json_decode() returned null. The checkout hangs and your client calls you at 2 AM. A better prompt won’t fix a race condition or a provider outage. A system will.
How an LLM control layer is put together
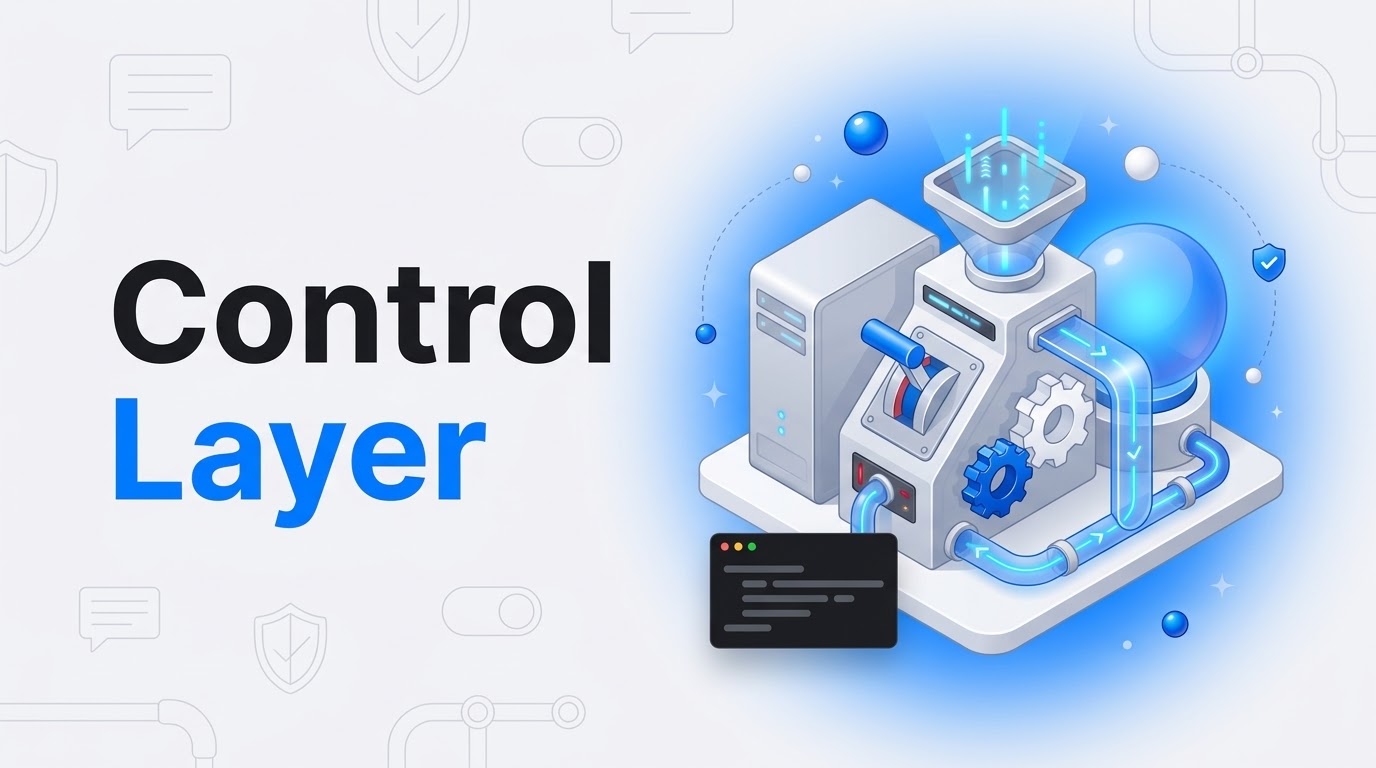
A production-ready LLM Control Layer is an orchestrator that sits between your application and the model. It doesn’t care how clever your prompt is. It cares whether the contract was met. In my experience, reliability comes less from the model and more from the eight components wrapped around it.

If you’re building performance-critical apps, you already know external API calls are the biggest bottleneck. This layer handles security (InputGuard), resource limits (TokenBudget) and resilience (CircuitBreaker) before the request ever reaches the model.
Component 1: The InputGuard
In WordPress we sanitize everything, so why make an exception for LLMs? The InputGuard scans for injection patterns, like the classic “ignore all previous instructions,” based on the OWASP LLM Top 10. If the input looks malicious, the request dies in microseconds, before it costs you an API call or opens the door to a jailbreak.
Component 2: The circuit breaker
If OpenAI goes down for 30 seconds while you have 50 concurrent users, your server threads hang until they time out. That’s how a small outage turns into a site-wide crash. I build the breaker on WordPress transients so the failure state is shared across processes.
<?php
/**
 * Simple Circuit Breaker for LLM API calls.
 */
function bbioon_check_llm_health() {
    $failures = (int) get_transient( 'bbioon_llm_failures' );

    // If we've hit 5 failures, "open" the circuit for 30 seconds.
    if ( $failures >= 5 ) {
        return false;
    }

    return true;
}

function bbioon_record_llm_failure() {
    $failures = (int) get_transient( 'bbioon_llm_failures' ) + 1;
    set_transient( 'bbioon_llm_failures', $failures, 30 );
}
Response validation isn’t optional
The LLM Control Layer needs a ResponseValidator, and checking that the output parses as JSON is only the start. It verifies the required keys and strips the markdown fencing models love to add. When validation fails, the RetryEngine takes the specific error (e.g., “Missing key: price”) and feeds it back to the model as a correction hint. That loop is what gets you from “maybe it works” to “it works every time.”
When I compared a naive integration against this system, the gap was huge. The naive version had a 0% pass rate on strict structured-output benchmarks under load, and the control layer hit 100%. It did add about 100ms of latency because of the retry logic, but in production I’ll pay that for correct output every time. For more on API overhead, see my guide on optimizing REST API performance.
If building an LLM control layer is eating your dev hours, I can handle it for you. I’ve been working with WordPress since the 4.x days.
My takeaway
Stop treating prompts like code. They’re probabilistic, not deterministic. If your application logic depends on LLM output, that output needs a software contract around it. Build the guardrails, add a Circuit Breaker pattern, and stop blaming the model for gaps in your architecture.